Automating the Autonomous: How Developers Are Using AlphaEvolve and Gemini to Optimize AI Coding Agent Skills

The landscape of software engineering is undergoing a quiet, fundamental transformation. Every single day, a rapidly expanding cohort of professional developers and enterprises turns to advanced coding agents—such as Google Antigravity and OpenCode—to shoulder the heavy lifting of writing, debugging, and maintaining software. Yet, as powerful as these artificial intelligence models have become, they remain fundamentally beholden to the quality of their instructions. An agent is only ever as effective as the inputs it receives. To extract maximum productivity from these systems, engineers have increasingly relied on "agent skills"—structured modules of instructions that guide models through complex workflows like building, testing, and deploying production code.
Despite their growing utility, crafting these skills has traditionally been an artisanal, manual endeavor. Developers write markdown files detailing protocols and best practices by hand, leaving them to guess whether their instructions actually move the needle on agent performance. Measuring the real-world impact of a given prompt or skill has historically lacked rigorous, scalable methodologies.
To bridge this gap, a team of researchers and engineers recently embarked on an experiment to systematically measure and optimize agent instructions. By pairing the OpenCode framework with Gemini 3.8 Flash and evaluating performance against the rigorous Terminal-Bench 2.0 public benchmark, the team sought to replace guesswork with empirical data. What they discovered fundamentally shifts how the industry understands the relationship between AI models, human-written instructions, and automated optimization loops.
The Baseline Challenge: Why General Advice Falls Short
When the team first initiated their testing protocols, they ran OpenCode powered by Gemini 3.8 Flash against tasks drawn directly from Terminal-Bench 2.0. The initial findings, however, proved decisively inconclusive. Using a standard, manually crafted baseline skill—a carefully structured checklist instructing the model to read first, reproduce failures, and work in small, verified steps—the coding agent successfully navigated roughly two-thirds of its assigned tasks.
Crucially, however, the agent achieved almost identical success rates when running without the skill entirely. The general advice contained within the human-written markdown files offered no measurable performance advantage over the raw capabilities of the underlying model.
This unexpected outcome highlighted a critical hypothesis regarding modern AI architecture: today’s state-of-the-art models and specialized coding agents are already heavily pre-trained and fine-tuned for software engineering tasks. Consequently, high-level, generalized advice provides little fresh utility to the model. The true performance gains, the researchers realized, do not lie in generic best practices, but in granular, highly specific operational protocols tailored to the exact failure modes of the agent. Finding those precise optimizations manually, however, is prohibitively time-consuming.
Introducing the Optimization Loop: AlphaEvolve Meets Harbor
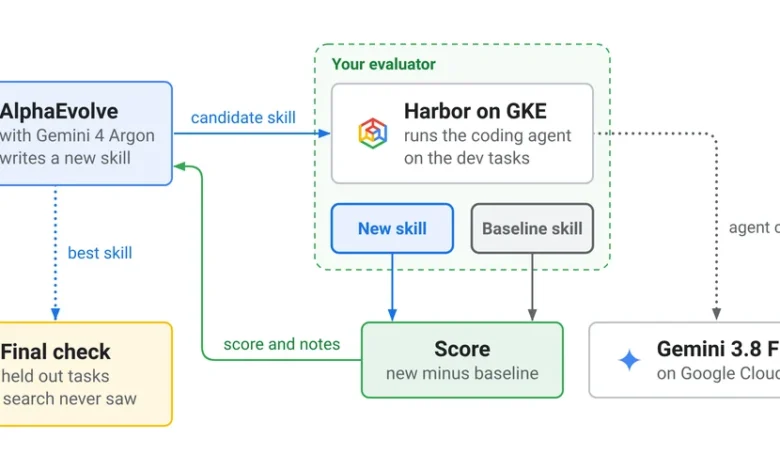
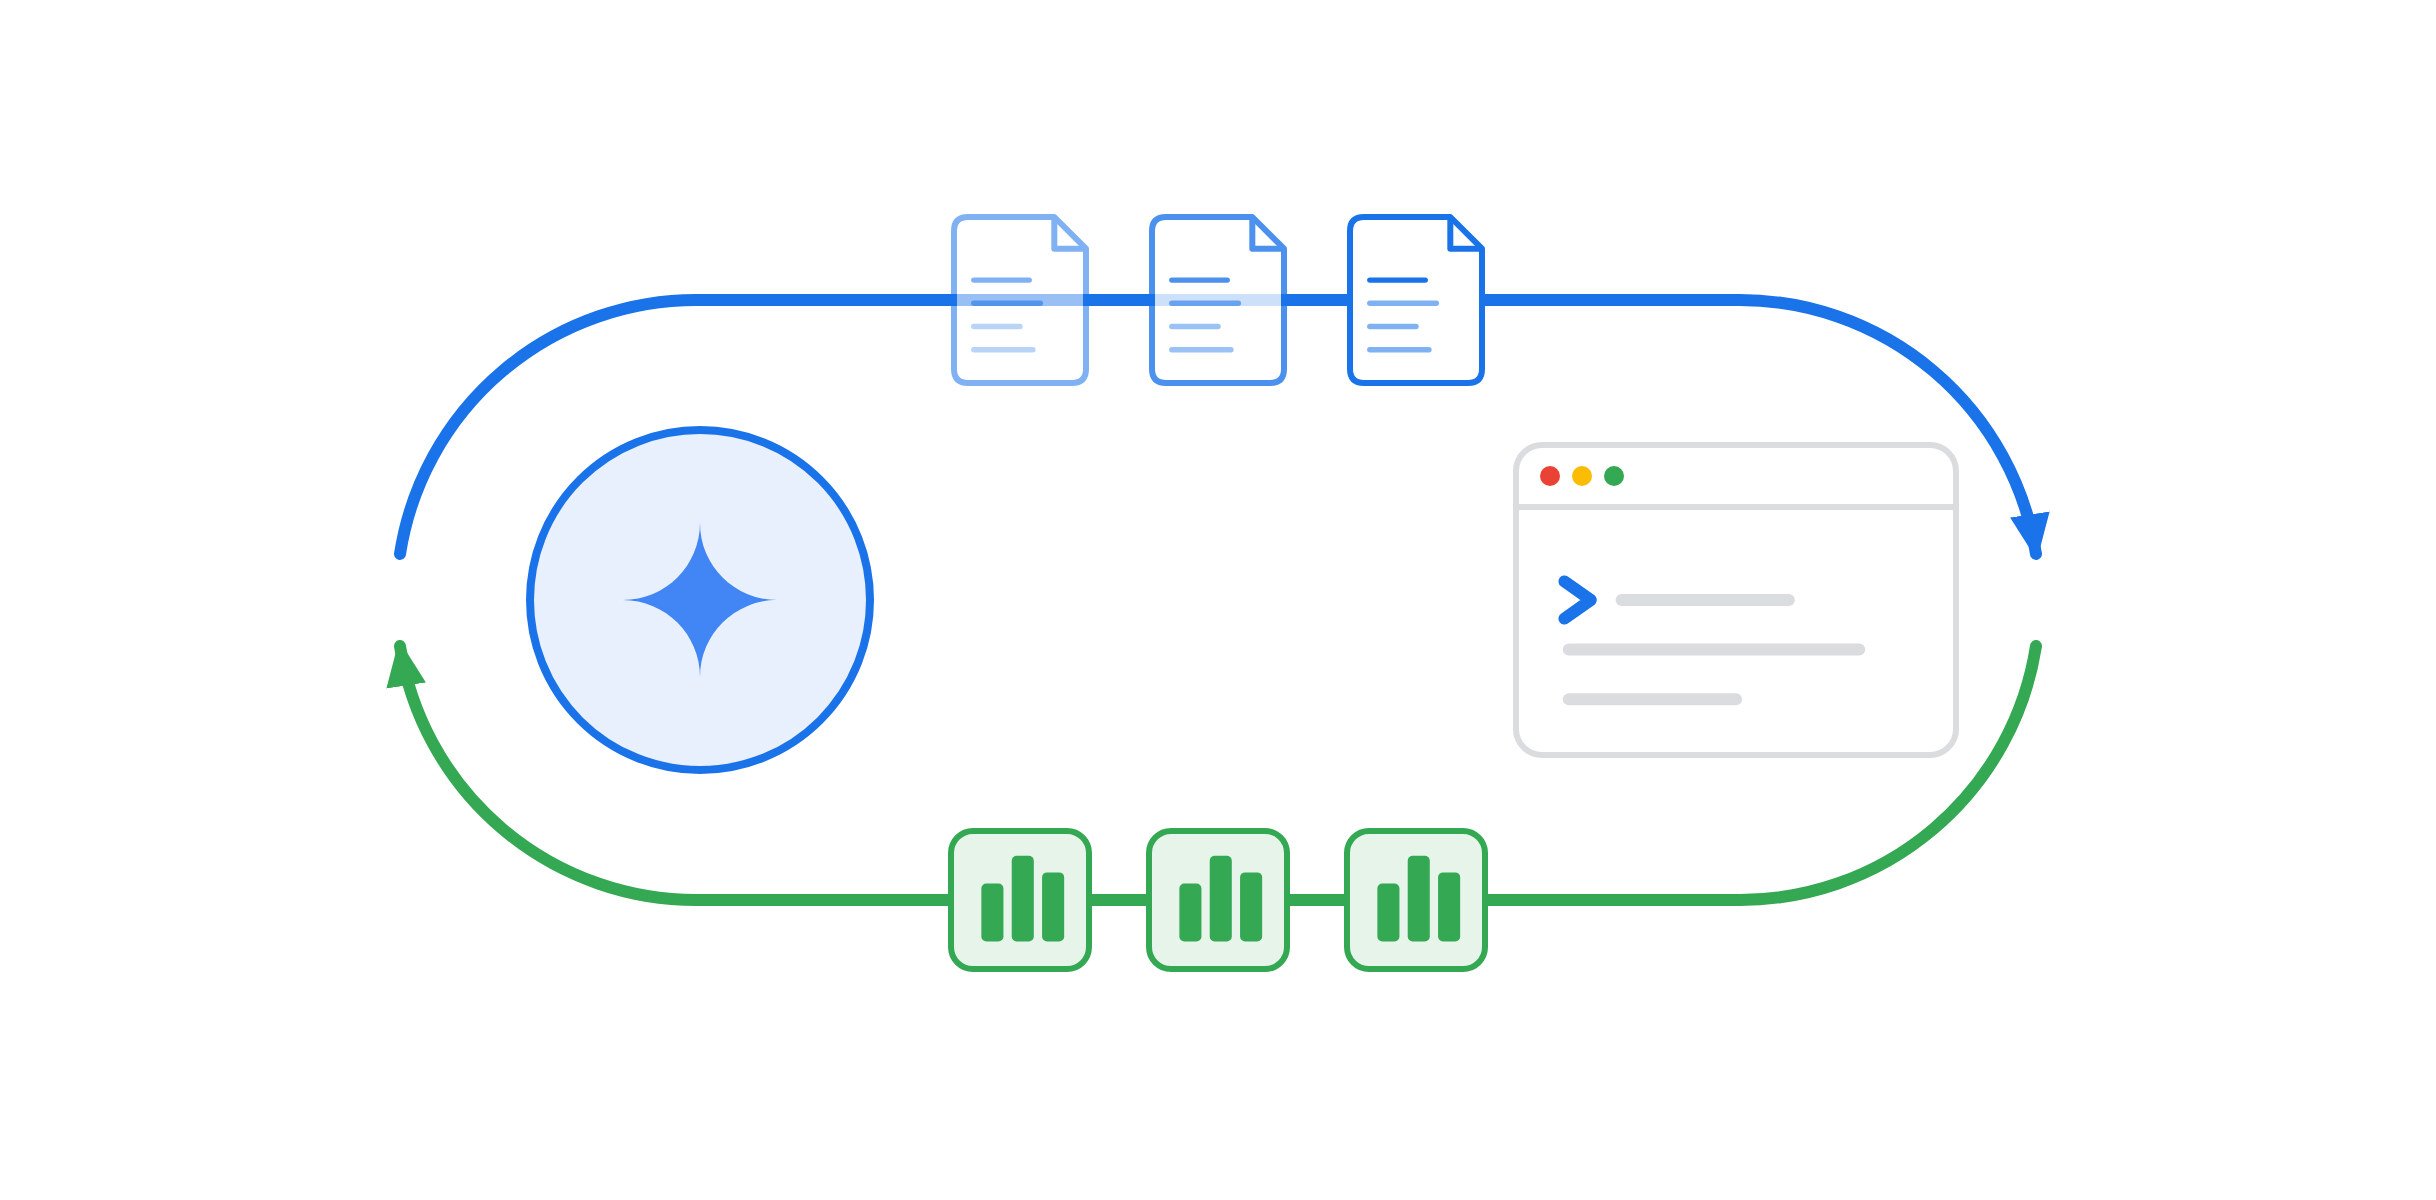
Faced with the limitations of manual prompt engineering, the engineering team turned to AlphaEvolve, an advanced optimization system traditionally deployed to refine complex code. AlphaEvolve operates on an evolutionary search principle: a generative model—in this case, Gemini—proposes a newly iterated version of a target program. An independent evaluator then tests and scores the proposal, and the search algorithm retains the higher-scoring variant for the next generation.
To adapt this framework for prompt engineering, the team treated the agent’s skill file—stored as a standard markdown document containing names, descriptions, and instructional text—as the "program" to be optimized. They placed the instructional text between designated markers that AlphaEvolve was programmed to parse and rewrite.
To evaluate these candidate skills at scale, the system integrated Harbor, an open-source evaluation framework capable of running coding agents on standardized benchmarks within isolated software containers. By deploying Harbor on Google Kubernetes Engine (GKE), the team spun up dedicated pods for individual trials, allowing a single automated search to execute thousands of distinct agent trials concurrently.
In this automated loop, every candidate skill is executed alongside a baseline skill on the exact same benchmark tasks. The evaluator returns definitive pass/fail scores alongside qualitative notes detailing why specific tasks failed or timed out. AlphaEvolve then funnels these diagnostic notes back to Gemini, informing the generation of the next, more refined iteration of the skill.
Ensuring Rigorous Measurement and Mitigating Noise
One of the foundational hurdles in automated prompt optimization is the inherent noisiness of agent scoring metrics. During early experimental runs, the team observed that model latency—fluctuations in how long the AI took to respond—accounted for a significant portion of the variance in candidate scores.
To neutralize this environmental noise and establish trustworthy scoring, the architecture mandated that every candidate skill be tested simultaneously against the baseline skill on identical tasks under identical network and hardware conditions. By evaluating candidates head-to-head rather than in isolation, the system could reliably isolate the true performance delta driven by the textual instructions rather than external variables.
Furthermore, the operational scale required to execute these searches introduced distinct infrastructure challenges. A single continuous search run spanning approximately ten hours pushed system limits: model latency occasionally throttled the evaluation pipeline, while massive volumes of granular agent logs rapidly consumed controller disk space. These bottlenecks underscore vital logistical lessons for engineering teams attempting to build similar automated optimization pipelines—chief among them the necessity of provisioning adequate log storage and designing resilient rate-limiting mechanisms to handle slow model response windows.
Empirical Results: Designing Around the Clock
As the evolutionary search progressed through multiple iterations, AlphaEvolve demonstrated a remarkable ability to home in on the agent’s most persistent operational vulnerability: time management.
Analysis of the evaluator’s diagnostic notes revealed that approximately one-third of all failed agent trials were cut short simply because they hit their execution time limits. Freed from the burden of writing generic checklists, AlphaEvolve’s automated search systematically pruned ineffective instructions and converged on a radically different style of skill protocol—one specifically engineered to optimize the agent’s time-allocation strategy, forcing it to triage problems efficiently and abandon doomed approaches before the clock ran out.
When tested against previously unseen development tasks, the optimized skills yielded tangible performance leaps. While the standard baseline skill offered no measurable improvement over zero-shot execution, skills refined through the AlphaEvolve loop added up to 33 points on complex development benchmarks. The data strongly suggests that modern models require hyper-specific, empirically derived behavioral constraints rather than intuitive human heuristics.
Expanding Horizons: From Code to Enterprise Workflows
Buoyed by these technical successes in software engineering benchmarks, researchers are actively expanding the application of AlphaEvolve beyond code repositories and into broader enterprise agent harnesses. This encompasses system prompts, compliance policy instructions, and tool-use protocols where foundational AI models naturally lack proprietary business rules or institutional context.
In initial pilot studies simulating customer service environments for a fictional financial institution, researchers intentionally planted erroneous policy rules within the agent’s instructions. AlphaEvolve successfully identified and corrected the faulty policy directives through automated search trials, seamlessly carrying those behavioral corrections over to unseen test scenarios. While other preliminary enterprise studies have yielded mixed results—prompting a cautious, phased rollout—the research team plans to publish comprehensive final findings upon the conclusion of their broader empirical investigations.
Implications for the Future of AI Development
The successful integration of AlphaEvolve, Harbor, and Gemini to automate the refinement of agent skills marks a significant milestone in the maturation of artificial intelligence engineering. By shifting prompt and skill engineering from a manual, trial-and-error discipline into an automated, evolutionary search science, developers can unlock unprecedented reliability from autonomous systems.
As organizations increasingly deploy coding agents and autonomous enterprise assistants into production environments, the ability to systematically optimize instructions based on empirical failure logs will become a core competency. The era of writing static markdown instructions and hoping for the best is drawing to a close; the future of agentic workflows belongs to self-optimizing systems that learn, test, and evolve on their own terms.