Optimizing LLM Performance Through Data Reshaping: Reducing Token Consumption with Markdown Output

The rapid evolution of autonomous AI agents has brought a hidden technical challenge to the forefront of the software industry: the exponential cost of token consumption. As agents become more sophisticated, they increasingly rely on deep web searches, file retrievals, and recursive data analysis. Each of these actions requires feeding large volumes of data into the model’s context window. Because large language models (LLMs) charge based on the number of tokens processed—regardless of whether that data is semantically relevant to the task—developers are finding that inefficient data structures are significantly bloating operational expenses and slowing down system performance.
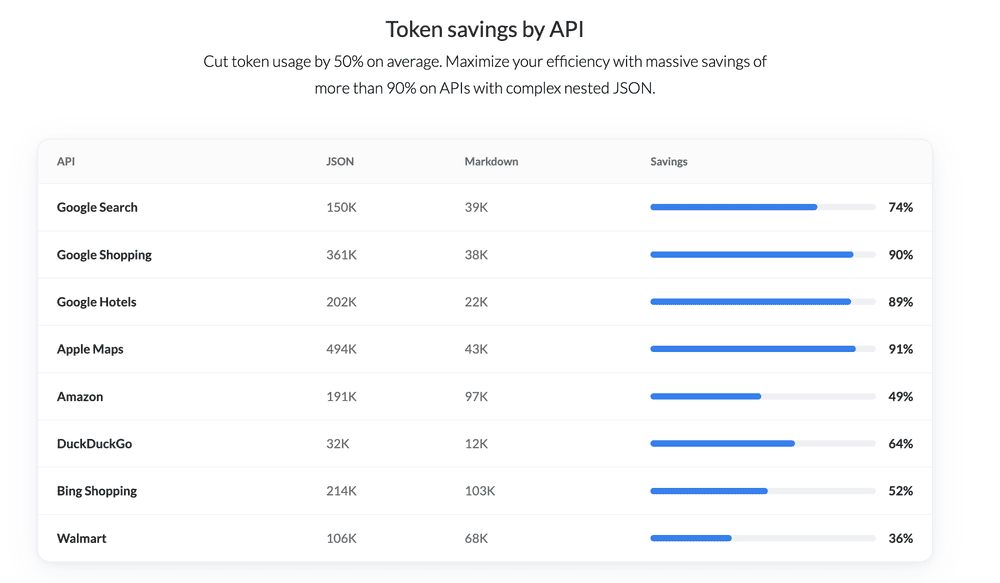
In a recent development aimed at mitigating this issue, SerpApi has introduced a Markdown output feature specifically designed to trim unnecessary overhead from search results. By shifting from traditional JavaScript Object Notation (JSON) to a streamlined Markdown format, developers can reduce the token count of search responses by up to 74 percent, fundamentally changing how AI systems interact with web-based data.
The Problem of Token Bloat in Agentic Systems
In modern AI architectures, agents often function by performing a search query and then analyzing the results. A typical search for a common term, such as "coffee shops," returns a wealth of data including tracking links, metadata, nested object structures, and internal logging information. When this raw data is piped directly into an LLM, the model must process the entire payload.
In a standard JSON response, much of this information is intended for machine-to-machine communication or front-end user interface rendering rather than semantic reasoning. For an LLM tasked with identifying a specific business, a nested JSON object containing pixel-tracking URLs or obscure database keys adds no value to the final output but consumes a significant portion of the context window. As these agents iterate through recursive loops or perform multi-step research, these wasted tokens accumulate, leading to "token bloat." This phenomenon not only inflates costs but also risks pushing critical information out of the context window, effectively forcing the model to "forget" earlier parts of a conversation or document.
Chronology of Data Delivery for AI
For years, JSON has been the industry standard for API communication. Its strict structure and data typing make it ideal for backend engineering, where precision is paramount. However, the rise of Generative AI has necessitated a shift in how data is delivered.
- The JSON Era (2000s–2023): Developers prioritized strict schema definitions. APIs were designed to feed databases and web frontends, where the priority was ensuring that integers were integers and strings were properly escaped.
- The LLM Transition (2023–Early 2024): Developers began feeding raw JSON directly into LLMs. While functional, this resulted in high latency and unexpected costs, as models spent compute power "reading" through boilerplate code and tracking metadata.
- The Optimization Phase (Mid-2024–Present): The industry is now seeing the emergence of model-friendly data formats. SerpApi’s implementation of Markdown output is a primary example of this shift, prioritizing the semantic signal-to-noise ratio over rigid structural requirements.
Analyzing the Efficiency Gap
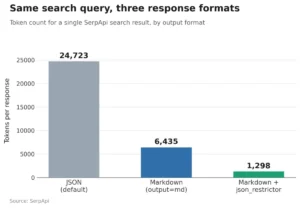
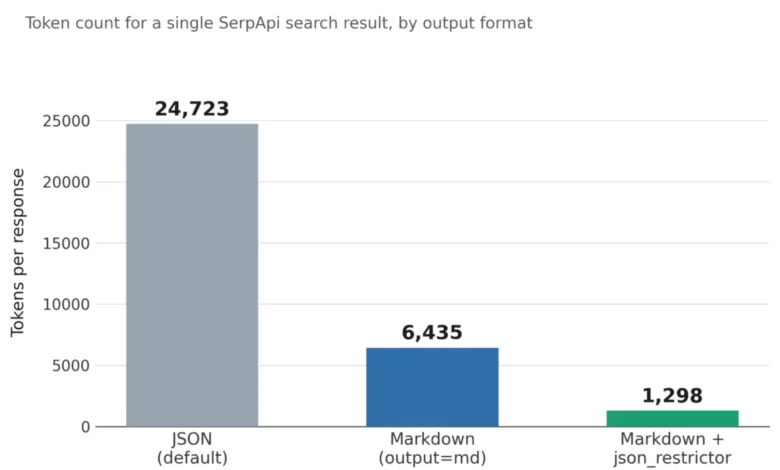
The impact of this transition is supported by concrete benchmarks. In a test case comparing JSON to Markdown outputs for a "coffee" search query, the data revealed a drastic divergence in token usage. The original JSON payload required 24,723 tokens to convey the information. When the same search was executed using SerpApi’s Markdown output, the requirement dropped to 6,435 tokens. A further, more restricted view brought the token count down to just 1,298.
This 74 to 95 percent reduction is not merely a cosmetic improvement; it has profound implications for the economics of AI deployment. For organizations running thousands of agentic queries per day, this reduction represents a substantial decrease in monthly API bills from model providers like OpenAI or Anthropic. Furthermore, by reclaiming space within the context window, developers can fit more complex instructions, longer historical context, or multiple retrieved documents into a single prompt, effectively boosting the agent’s "reasoning" capabilities without upgrading to a more expensive, higher-context model.
Understanding the Mechanism: What Gets Removed?
The logic behind Markdown optimization is simple: strip away what a human or a reasoning agent doesn’t need to understand. JSON often includes a variety of fields that serve programmatic purposes—such as CSS classes, complex coordinate arrays for mapping, and redundant tracking headers.
Markdown, by contrast, transforms these into readable tables and plain text blocks. By eliminating the "noise" that exists solely for code to parse or for a UI to render, the data remains human-readable while becoming significantly leaner for an LLM to digest. The removal of verbose, nested keys and the flattening of complex data hierarchies are the primary drivers of this efficiency.
Where Precision Still Requires JSON
Despite the efficiency gains, industry experts warn that Markdown is not a universal replacement for structured data. In pipelines where downstream processes require high precision, JSON remains indispensable.
For instance, if a financial agent is tasked with analyzing stock prices or performing arithmetic on currency values, it requires the exact data types that JSON provides. If a piece of software relies on a specific float for a rating or an array of integers for a time series, converting that data to Markdown could lead to parsing errors. Consequently, the industry is moving toward a hybrid approach: using Markdown for summarization and "discovery" tasks, while retaining JSON for data-intensive, logic-heavy workflows.

Implementation and Future Implications
SerpApi has integrated this feature into its existing API architecture, allowing developers to switch between formats by modifying query parameters or headers. This flexibility is critical for developers who need to toggle between "exploration" (Markdown) and "extraction" (JSON) based on the specific requirements of the AI task at hand.
The broader implication of this trend is a fundamental change in the relationship between API providers and AI developers. As token costs remain a bottleneck for mass-market AI adoption, providers are being pushed to become "model-aware." This means designing APIs that understand not just what the data is, but how the consumer—in this case, an LLM—actually processes it.
Strategic Recommendations for Developers
For engineering teams looking to optimize their own AI agents, the following steps are recommended:
- Audit Token Consumption: Before optimizing, identify the most expensive calls in your pipeline. Tools that measure token usage per request are essential for establishing a baseline.
- Reshape Payloads: If using APIs, check for "fields" or "restrictor" parameters that allow you to exclude unnecessary data on the server side.
- Test Format Agnostic Payloads: Experiment with different formats (Markdown, YAML, or plain text) to see which yields the lowest token count without sacrificing the quality of the model’s reasoning.
- Prioritize Semantic Signal: Evaluate whether your model needs the raw data or a summary. Often, a well-formatted summary contains all the necessary information for a decision, removing the need for deep, nested data structures.
The transition toward optimized data formats marks a maturing of the AI ecosystem. As the industry moves past the initial "experimental" phase, the focus is shifting from simple functionality to efficiency, reliability, and cost-effectiveness. By reconsidering the structure of the data feeds that power autonomous agents, developers can ensure their systems remain competitive, scalable, and economically sustainable in an increasingly token-constrained environment.
Related posts: