Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head

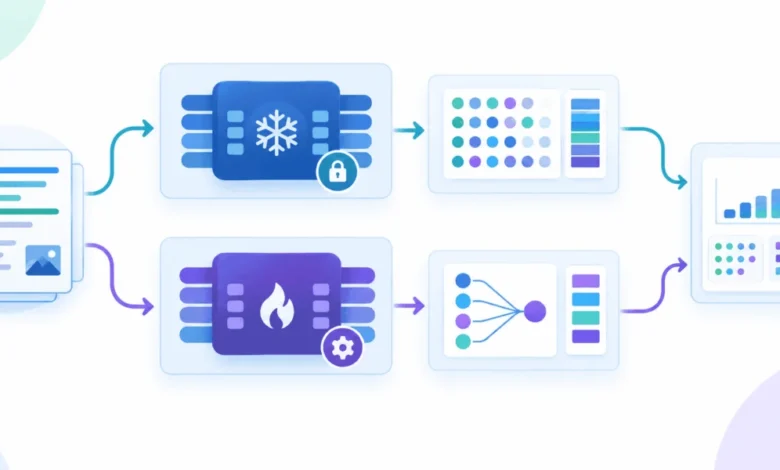
The rapid proliferation of Large Language Models (LLMs) has fundamentally altered the landscape of natural language processing (NLP). As organizations increasingly look to deploy proprietary AI solutions, a critical architectural decision emerges: should one commit to the resource-intensive process of fine-tuning a foundational model, or is it more efficient to utilize frozen embeddings paired with a lightweight downstream classifier? This debate is not merely academic; it sits at the heart of balancing model performance, operational expenditure, and time-to-market for modern AI applications.
The Evolution of Model Adaptation
Historically, the machine learning community relied on training task-specific models from scratch. With the advent of Transformer architectures, the paradigm shifted toward "pre-train then fine-tune." However, as models like Llama-3, Qwen, and Mistral grow in parameter count, full fine-tuning has become prohibitively expensive for most enterprises.
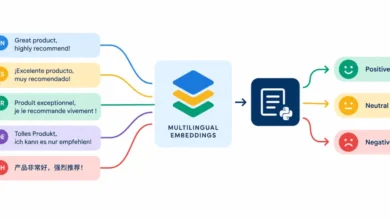
The introduction of Parameter-Efficient Fine-Tuning (PEFT) methods, specifically Low-Rank Adaptation (LoRA), provided a middle ground. By injecting trainable rank-decomposition matrices into the transformer layers, engineers can adapt models with only a fraction of the trainable parameters. Conversely, the "frozen embedding" approach treats the LLM as a static feature extractor, generating vector representations of input data that are subsequently fed into traditional machine learning algorithms like Random Forests or Support Vector Machines (SVMs) via libraries such as scikit-learn.
Comparative Analysis: Methodology and Performance
To evaluate these strategies, a standardized test using the AG News dataset—a collection of over 120,000 news articles categorized into four distinct labels—provides a clear benchmark. By utilizing a 1.5-billion parameter model as the backbone, researchers can observe the variance in both computational cost and predictive accuracy.
In the frozen embedding approach, the LLM remains untouched. The process involves passing text inputs through the model to retrieve the hidden state of the final token. This vector representation encapsulates the semantic nuances of the input. When these vectors are fed into a Random Forest classifier, the model training is near-instantaneous. In practical tests, this approach typically achieves accuracy rates in the 80% to 85% range, depending on the richness of the underlying pre-trained embeddings.
In contrast, LoRA fine-tuning modifies the internal weights of the LLM. By configuring a training loop with 4-bit quantization (QLoRA), developers can run this process on consumer-grade hardware like an NVIDIA T4 GPU. While this approach often yields a performance increase—frequently pushing accuracy toward the 87% to 90% range—it requires a significantly longer training duration. The computational overhead is not just in the training cycles, but also in the management of optimizer states and the increased memory requirements during the backpropagation process.
Chronology of Implementation
The implementation timeline for these two strategies highlights the operational divide:
- Phase 1: Environment Setup. Both methods require the installation of specialized libraries, including
transformers,peft,bitsandbytes, andscikit-learn. The initial setup is identical, emphasizing the need for GPU-accelerated environments to manage the model’s weight tensors. - Phase 2: Feature Extraction vs. Adapter Integration. In the frozen approach, the system runs in inference-only mode. No gradient calculation occurs, which protects the GPU memory. In the LoRA approach, the developer must define the rank (r) and alpha parameters, essentially determining the capacity of the trainable adapter.
- Phase 3: Optimization. For frozen embeddings, the training phase is a traditional scikit-learn fit command. For LoRA, the process involves a
Trainerobject, managing epochs, batch sizes, and learning rate schedulers. - Phase 4: Evaluation. The final step measures the F1-score or accuracy against a hold-out test set.
Economic and Technical Implications
From a business perspective, the choice between these two methods hinges on the "cost of accuracy."
The frozen embedding strategy is highly scalable. Because the LLM does not change, it can be hosted in a multi-tenant environment, serving embeddings to various downstream classifiers simultaneously. This reduces the infrastructure footprint significantly. It is the ideal candidate for applications where the domain-specific nuances are subtle and a "good enough" classification performance is acceptable.
Conversely, LoRA fine-tuning is necessary when the model must exhibit behaviors that are not present in its base training data. For example, if a company is building a custom legal document classifier where specific terminology is critical, frozen embeddings might fail to capture the highly specialized semantic relationships that a fine-tuned model would internalize.
Expert Perspectives and Industry Trends
Leading AI researchers have noted that the industry is trending toward a "modular" approach. "The goal is to keep the backbone as stable as possible," suggests one lead engineer at a prominent NLP lab. "If you can solve your problem with a linear head on top of a frozen model, you avoid the risk of ‘catastrophic forgetting,’ where the model loses its general knowledge while trying to specialize in a narrow domain."
However, others argue that as hardware costs continue to decrease and specialized hardware for inference becomes more efficient, the overhead of fine-tuning will eventually become negligible. We are currently in a transition phase where the choice is dictated by the immediate constraints of the hardware environment rather than the theoretical limits of the model.
Broader Impact on AI Deployment
The implications of this choice extend to the long-term maintenance of AI systems. A system relying on frozen embeddings is easier to update; if the underlying LLM is updated to a newer version, the downstream classifier remains compatible with minimal changes. If a system is fine-tuned via LoRA, the adapter is tightly coupled to the specific version of the base model. If the base model architecture changes, the fine-tuned adapter often becomes obsolete, necessitating a complete re-training cycle.
Furthermore, data privacy and security play a role. By using frozen embeddings, the sensitive data is only processed by the LLM in inference mode, reducing the risk of data leakage during the training phase. Fine-tuning, even with PEFT methods, requires exposing the model to the training data in a way that creates updated weights, which could potentially memorize sensitive training inputs if not properly regularized.
Conclusion: A Strategic Decision
Ultimately, the decision to fine-tune versus use frozen embeddings is a reflection of the specific requirements of the deployment. For high-throughput, low-latency, and cost-sensitive applications, frozen embeddings provide a robust and efficient solution. For complex, high-accuracy requirements where domain-specific semantic understanding is paramount, QLoRA fine-tuning remains the gold standard.
As the ecosystem matures, we can expect to see more hybrid approaches, where dynamic adapters are swapped in and out based on the incoming query, combining the stability of frozen models with the precision of fine-tuned experts. Organizations must carefully audit their specific use cases, compute budgets, and accuracy targets before committing to a long-term architectural path. In an era where AI development is synonymous with agility, the ability to choose the correct adaptation strategy is as important as the model selection itself.