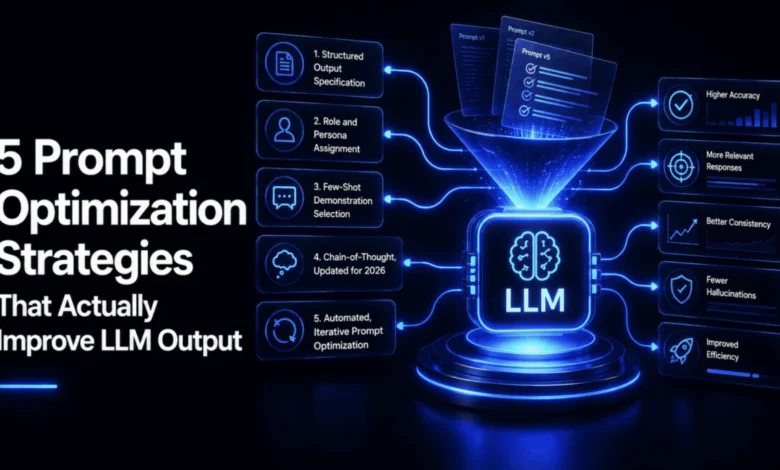
The distinction between prompt engineering and prompt optimization has increasingly become a critical point of discussion among software engineers and artificial intelligence practitioners deploying large language models (LLMs) into production environments. While prompt engineering typically involves designing instructions from a blank slate, prompt optimization focuses on refining existing prompts through targeted adjustments in specificity, structural formatting, and iterative evaluation without altering the underlying model architecture. This methodological difference addresses a fundamental challenge for developers: most production systems do not suffer from a lack of initial prompts, but rather from prompts that yield inconsistent, unparseable, or subtly incorrect outputs. Industry adoption of generative AI has accelerated the need for rigorous, evidence-based prompt refinement techniques, moving the discipline away from intuitive guesswork toward systematic engineering.
To understand the practical application of prompt optimization, industry analysts often examine text-processing tasks that feature real-world conversational ambiguity. Consider a typical corporate meeting transcript involving three participants—Priya, Tom, and Jake—discussing a checkout redesign, a billing service migration, and customer support queues. The transcript contains complex conversational dynamics: a task assigned to Priya is reassigned mid-conversation to Jake, a secondary technical requirement regarding a tablet breakpoint is integrated into the existing review rather than being spun off as a separate ticket, and the ownership of a support-queue triage task is explicitly left unresolved rather than falsely attributed. In software development and data extraction workflows, an LLM prompt that handles the straightforward elements of such a text while failing these edge cases represents a critical point of failure, particularly when downstream systems rely on absolute accuracy.
Specifying Structured Output for Production Reliability
The implementation of structured output represents one of the most quantifiable levers available in prompt optimization. In enterprise environments, instructing an LLM to generate plain text summaries or numbered prose introduces significant operational risk. Downstream software systems require parsable data structures, such as JSON schemas validated through libraries like Pydantic, to function reliably. Unparseable output creates hard failures in data pipelines rather than minor inconveniences.
When developers implement strict schema validation, raw textual responses fail to parse when formatted as conversational prose, regardless of how readable the text appears to a human user. Conversely, enforcing an explicit schema ensures that extracted entities map directly to predefined data types, including owners, tasks, and deadlines. This transition from natural language prose to programmatic schemas eliminates the need for manual human transcription and guarantees that automated systems can consume the generated data without disruption.
Assigning Roles and Personas to Guide Contextual Focus
The integration of specific role assignments within a prompt modifies how a model’s learned representations are activated during inference. Rather than issuing a generic instruction to extract information, assigning a defined professional persona primes the model to anticipate domain-specific complexities.
For instance, instructing an LLM to operate as an experienced executive assistant who is accustomed to mid-sentence conversational shifts and unassigned action items fundamentally alters its approach to parsing ambiguous transcripts. Without a defined persona, generic prompts rely on surface-level pattern matching, frequently capturing initial assignments while missing subsequent corrections. Priming the model with contextual awareness regarding human conversational patterns ensures heightened vigilance toward complex dialogue flows, thereby reducing downstream extraction errors.
Selecting Few-Shot Demonstrations via Diversity-Aware Algorithms
Research into prompt optimization indicates that the selection of few-shot demonstrations often exerts a greater influence on output quality than the phrasing of the primary instruction itself. A common pitfall in prompt design is the inclusion of multiple examples that reflect identical structural patterns, which fails to expand the model’s contextual understanding.
To maximize the efficacy of few-shot sets, advanced engineering teams employ algorithmic selection methods, such as TF-IDF vectorization and cosine similarity calculations, to curate candidate examples. By identifying and filtering out near-duplicate examples from a candidate pool, developers can construct a diverse set of demonstrations that cover distinct structural scenarios—such as confirmed ownership, explicitly unassigned tasks, and merged deliverables. This methodological approach ensures that the model learns from a comprehensive spectrum of operational patterns rather than redundant variations of a single base case.
Calibrating Chain-of-Thought Reasoning for Complex Ambiguities
Chain-of-thought (CoT) prompting, which requires an LLM to articulate its reasoning steps prior to generating a final answer, has evolved alongside frontier model architectures. While modern LLMs often perform internal reasoning natively, explicit CoT instructions remain highly valuable when processing highly ambiguous inputs where surface-level pattern matching fails.
In scenarios involving dynamic task reassignments, unprompted models frequently latch onto initial statements while ignoring subsequent revisions. By incorporating a reasoning step that explicitly directs the model to trace ownership across the entirety of the dialogue before reporting a final decision, developers can mitigate premature conclusion generation. Furthermore, to address cost and latency considerations associated with verbose reasoning tokens, emerging techniques such as "Chain of Draft" enable models to articulate concise, abbreviated reasoning steps that preserve analytical accuracy while significantly reducing computational overhead.
Executing Automated Iterative Prompt Optimization
The pinnacle of prompt optimization methodology involves transitioning from manual, heuristic-based adjustments to automated search processes. By treating prompt fragments as candidate variables, engineering teams can evaluate prompt variations against ground-truth test datasets using composite scoring functions.
Automated optimization frameworks typically employ hill-climbing search algorithms to iteratively evaluate candidate instruction fragments. These frameworks score extractions based on metrics such as recall, owner accuracy, and penalties for fabricated data items. Empirical evaluations demonstrate that automated search processes can efficiently identify the minimal set of corrective instructions required to achieve optimal extraction accuracy, preventing the common practice of overburdening prompts with excessive, redundant instructions.
Broader Industry Implications and Future Outlook
The maturation of prompt optimization from an intuitive art form into a rigorous engineering discipline reflects the broader professionalization of artificial intelligence deployment. As enterprises increasingly rely on LLMs to automate complex data extraction, customer support routing, and internal operations, the tolerance for silent failures diminishes. Unresolved ownership assignments, missed task migrations, and unparsed data formats translate directly to operational friction, financial loss, and compromised data integrity.
Industry analysts emphasize that adopting systematic optimization frameworks—ranging from strict schema enforcement and diversity-aware few-shot selection to automated hill-climbing search processes—enables organizations to scale their AI initiatives reliably. By replacing guesswork with measurable, empirical validation, software engineering teams can construct robust LLM pipelines capable of maintaining high performance standards in complex, real-world operational environments.