Accelerating Narrow Automation: Optimizing Small Language Models with Prompt Prefix Key-Value Caching

In the rapidly evolving landscape of artificial intelligence engineering, deploying Large Language Models (LLMs) and Small Language Models (SLMs) for production-grade narrow automation frequently exposes severe performance bottlenecks. System architects designing automated workflows—such as customer support ticket routing, document classification, or automated data extraction—often rely on structured, highly repetitive prompt templates. These prompts typically feature exhaustive system instructions, precise taxonomy definitions, and extensive few-shot examples, succeeded only by a variable trailing payload containing the specific item for evaluation. Standard inference execution pipelines conventionally recompute the entirety of this input sequence for every discrete API call or batch item. This redundant processing architecture introduces unnecessary computational overhead, increases latency, and inflates infrastructure operational expenses.
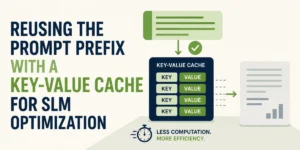
To address these inefficiencies, machine learning engineers are increasingly adopting advanced optimization strategies tailored specifically for edge and resource-constrained environments. Following previous investigations into constraining output spaces to streamline small language model classification, industry research has turned toward key-value (KV) cache reuse for static prompt prefixes. By computing the key and value vectors of a static instruction block exactly once and retaining them in memory, developers can bypass redundant pre-fill computations entirely. Benchmarks utilizing the lightweight Qwen2.5-0.5B-Instruct model demonstrate that this optimization technique yields a remarkable 57 percent reduction in overall execution time during batch classification tasks, transforming compact models into viable, high-performance engines for high-throughput enterprise automation.
The Mechanics of Redundancy in Transformer Architectures
To comprehend the necessity of prefix caching, one must examine the fundamental mechanics of transformer-based neural networks. During the inference pre-fill phase, a transformer processes an input sequence of tokens simultaneously, generating key and value vectors for every token across every self-attention layer of the network. Critically, the mathematical computation of a key or a vector for any given token depends exclusively on the tokens positioned to its left.
In narrow automation paradigms, prompt structures are exceptionally static. For instance, a customer support classification prompt may incorporate a 145-token instruction block outlining operational taxonomies and classification guidelines, while individual incoming support tickets contribute a mere 20 to 22 tokens of dynamic content. In this scenario, approximately 87 percent of every processed prompt remains byte-for-byte identical across consecutive inference requests.
Under standard operating procedures, when a system processes 600 sequential support tickets using an unoptimized inference loop, the model redundantly computes the key-value representations of those initial 145 tokens 600 separate times. On resource-constrained hardware—such as an Apple M2 MacBook Air equipped with 24GB of RAM and a 16-core Neural Engine running float16 precision weights via Hugging Face Transformers—this repetitive mathematical overhead accumulates rapidly. Empirical evaluations indicate that fully re-encoding the entire prompt for each evaluation cycle requires an average of 308.1 milliseconds per item, culminating in a total execution time of 184.85 seconds for a 600-item validation set.
Implementing Prefix Caching via DynamicCache
To eliminate this computational redundancy, modern deep learning frameworks support explicit management of past key-value states through modular cache structures, such as the DynamicCache class available within the Hugging Face ecosystem. Rather than treating each inference invocation as an isolated, stateless event, developers can initialize the model, pass the static system instruction block through the network a single time, and persistently store the resulting attention keys and values in memory.
When processing subsequent individual items, the execution pipeline isolates the dynamic suffix—the incoming support ticket—and feeds only those new tokens into the model. However, successfully executing this operation requires meticulous alignment of tensor dimensions, attention masks, and cache positions. The attention mask must be explicitly constructed to encompass both the cached historical prefix and the incoming suffix tokens. Furthermore, the model must be explicitly instructed via cache_position parameters that the newly introduced tokens commence at an index matching the length of the static prefix rather than resetting to zero.
Upon completing the forward pass for a given ticket and extracting the necessary output logits—frequently optimized through constrained decoding strategies that evaluate only the first token IDs of distinct target categories—the cache is systematically rolled back to its baseline state. Utilizing the crop() method, the system trims the dynamically appended suffix tokens from the KV cache, restoring it to the exact state generated by the static instruction block. This ensures that the subsequent item begins its evaluation immediately from the pre-computed prefix, preserving correctness while drastically slashing execution overhead.
Comparative Performance Metrics and Efficiency Gains
Rigorous benchmarking validates the substantial performance dividends yielded by prompt prefix caching. When executing a comparative evaluation across 600 toy customer support records using the Qwen2.5-0.5B-Instruct architecture, the performance divergence between naive re-encoding and prefix caching is pronounced.
In the baseline configuration, where the complete prompt is re-encoded on every iteration, the execution time stabilizes at approximately 0.31 seconds per ticket, totaling 184.85 seconds for the complete evaluation suite. Conversely, when deploying the persistent DynamicCache strategy, the per-item processing latency drops to approximately 0.13 seconds. The aggregate execution time for the identical 600-item workload plummets to 80.07 seconds. This represents an overall runtime reduction of approximately 57 percent.
Crucially, this performance enhancement is achieved without compromising the accuracy or determinism of the model’s outputs. Because prefix caching is a purely mathematical optimization designed to bypass redundant floating-point operations rather than alter model weights or sampling heuristics, the classification predictions generated by the cached architecture match the baseline outputs identically across every test case.
Furthermore, the economic and operational advantages of this technique scale proportionally with the complexity and length of the prompt instructions. In enterprise environments where system instructions, policy guidelines, and few-shot examples span thousands of tokens to ensure high-accuracy classification, unoptimized inference becomes cost-prohibitive. Prefix caching inverts this dynamic: as instruction blocks grow longer and more detailed, the relative proportion of static tokens increases, magnifying the efficiency gains and making expansive, highly-constrained prompts computationally economical.
Broader Implications for Enterprise Narrow Automation
The successful optimization of small language models through architectural techniques like prefix caching marks a significant maturation point for enterprise AI deployment strategies. Historically, organizations seeking to automate narrow, high-volume operational workflows faced a difficult compromise. Deploying massive, billion-parameter general-purpose foundation models via cloud APIs offered high accuracy but introduced prohibitive latency, unpredictable cost structures, and severe data privacy vulnerabilities. Conversely, deploying smaller models locally or on edge infrastructure frequently necessitated compromises in reasoning capability or prompt complexity to maintain acceptable throughput.
By leveraging advanced memory management techniques—such as constrained output decoding combined with key-value cache reuse—developers can bridge this performance gap. Small language models operating on modest hardware configurations can achieve inference speeds that rival or exceed traditional software automation scripts, all while maintaining the flexible, natural language understanding capabilities characteristic of modern generative AI.
Industry analysts note that as edge computing and localized AI deployments accelerate across financial services, healthcare, logistics, and customer relationship management, optimization strategies that maximize hardware utilization will become standard engineering practice. The transition from stateless, brute-force prompt execution to stateful, cache-aware inference pipelines signals that small language models are no longer viewed merely as degraded substitutes for larger systems, but rather as precision-engineered tools uniquely optimized for scalable enterprise automation.