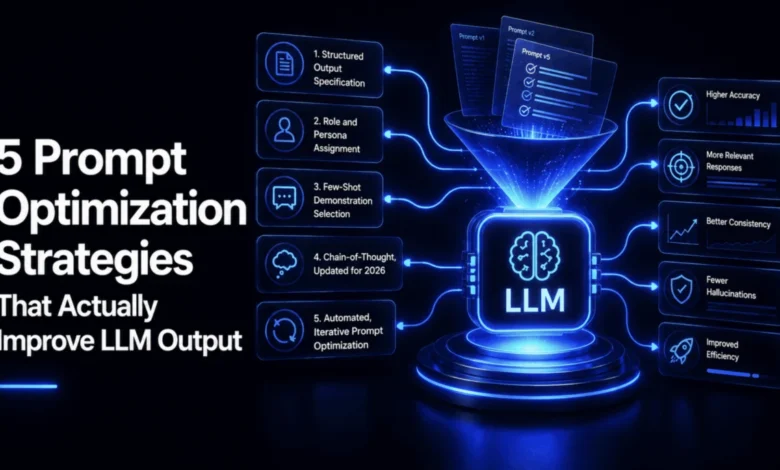
The rapid commercial adoption of Large Language Models (LLMs) across enterprise software engineering, customer operations, and data analytics has brought a persistent methodological ambiguity to the forefront of artificial intelligence deployment: the distinction between prompt engineering and prompt optimization. While industry discourse frequently treats these terms as synonyms, software architecture and AI implementation standards dictate a sharp conceptual separation. Prompt engineering primarily encompasses the initial authoring of generative instructions from a blank-page framework, establishing the baseline parameters under which a model interprets a task. Conversely, prompt optimization relies on iterative refinement, structural formatting, linguistic specificity, and empirical evaluation to elevate the performance of an already functioning prompt without modifying the underlying model weights or architecture.
For developers, product managers, and data scientists operating in production environments, this distinction carries significant operational weight. Most integration challenges do not stem from a complete absence of instruction, but rather from the persistent inadequacy of working prompts that produce unreliable, unparseable, or subtly inaccurate outputs. Addressing these deficiencies requires moving past intuitive adjustments and folk wisdom, adopting instead a rigorous, evidence-backed framework of systematic optimization. By evaluating prompt modifications against deliberately complex, ambiguous real-world scenarios—such as messy, multi-party meeting transcripts featuring mid-conversation reassignments, unresolved ownership, and contextual merging of tasks—engineering teams can transition from trial-and-error adjustments to predictable, measurable output validation.
The Operational Mechanics of Structural Output and Pydantic Validation
The foundational vulnerability of natural language interfaces in enterprise pipelines lies in the ambiguity of unstructured prose. When an LLM is tasked with extracting action items or data points from a transcript through an open-ended request, the resulting response is typically rendered in fluent, readable natural language. While this satisfies human cognitive requirements during manual review, it introduces a severe vulnerability for downstream software systems: unparseable output. In high-volume production environments, a failure to conform to strict data schemata is not a minor cosmetic inconvenience, but a hard system failure that halts automated execution workflows.
To mitigate this risk, modern AI systems integrate explicit structured output constraints enforced through data validation frameworks such as Pydantic. By requiring the model to return data that maps directly to predefined classes—defining exact data types for attributes such as owners, tasks, and deadlines—developers can implement rigorous validation functions. For example, a validation function checking a raw JSON string against an ActionItemList schema can immediately intercept anomalies. When tested against ambiguous text, unstructured prompts consistently fail automated ingestion protocols because prose cannot be reliably mapped to relational databases or API payloads regardless of its human-readable fluency. Conversely, enforcing explicit schema constraints ensures that the data is either programmatically usable or safely flagged for exception handling, bypassing the need for manual transcription.
from pydantic import BaseModel, ValidationError

class ActionItem(BaseModel):
    owner: str
    task: str
    due: str

class ActionItemList(BaseModel):
    action_items: list[ActionItem]

def parse_structured_output(raw_json: str) -> tuple[ActionItemList | None, str | None]:
    """Validates a model's raw output against the schema. Returns the
    parsed object or a clear error, never a silent partial result."""
    try:
        return ActionItemList.model_validate_json(raw_json), None
    except ValidationError as e:
        return None, str(e)
Contextual Priming via Role Assignment and Persona Calibration
Beyond structural constraints, the way an instruction is framed dictates which segments of a model’s underlying neural pathways are activated during inference. Generic commands—such as a directive to extract action items from a transcript—rely entirely on the model’s generalized training distributions, often resulting in surface-level pattern matching that overlooks conversational nuances. By assigning a specific professional persona, developers can prime the model to anticipate domain-specific complexities before the parsing process begins.
For instance, transitioning from a generic instruction to a role-based prompt—such as casting the model as a meticulous executive assistant experienced in managing dynamic corporate dialogues—fundamentally alters output reliability. Transcripts frequently contain mid-sentence corrections, reassigned responsibilities, and items that are intentionally left unassigned when no participant steps forward. A generic prompt lacks the contextual bias required to track these shifts, frequently defaulting to the first individual mentioned in connection with a task. A calibrated persona prime, however, explicitly alerts the model to watch for conversational ambiguity, reducing the incidence of fabricated data and unassigned owner omissions.
Dynamic Few-Shot Demonstration Selection
The selection of few-shot examples represents one of the most high-impact variables in prompt optimization, frequently eclipsing the influence of instruction wording itself. Empirical research into in-context learning indicates that combining well-structured instructions with deliberately chosen demonstrations yields superior performance compared to either method deployed in isolation. However, a widespread engineering pitfall involves the random or naive inclusion of examples that fail to capture the spectrum of edge cases present in production data.
If a few-shot demonstration set accidentally comprises near-duplicate variations of the same straightforward pattern—such as multiple instances where an owner immediately confirms a high-priority deadline—the model derives minimal new information from the supplementary slots. To maximize the utility of few-shot learning, engineering teams utilize algorithmic selection methods, such as TF-IDF vectorization combined with cosine similarity metrics, to curate demonstrably diverse examples.
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity

def select_diverse_examples(candidates: list[str], k: int = 3) -> list[str]:
    """Greedily picks k examples that are maximally dissimilar from each
    other, so the few-shot set covers different patterns instead of
    k near-duplicates of the same case."""
    vectorizer = TfidfVectorizer(stop_words="english")
    vectors = vectorizer.fit_transform(candidates)
    similarity_matrix = cosine_similarity(vectors)

    selected_idx = [0]
    while len(selected_idx) < k:
        remaining = [i for i in range(len(candidates)) if i not in selected_idx]
        scores = [(i, 1 - max(similarity_matrix[i][j] for j in selected_idx)) for i in remaining]
        best_idx = max(scores, key=lambda pair: pair[1])[0]
        selected_idx.append(best_idx)
    return [candidates[i] for i in selected_idx]
By filtering out redundant candidates, developers ensure that the few-shot set covers distinct structural patterns: one instance featuring a clearly confirmed owner, another illustrating an explicitly unresolved assignment, and a third demonstrating the integration of a secondary task into an existing review item. This diversity forces the model to generalize its extraction logic rather than memorizing a single rigid template.
The Evolution of Chain-of-Thought Reasoning and Cost Efficiency
Chain-of-thought (CoT) prompting—the practice of instructing a model to articulate its step-by-step reasoning before delivering a final answer—has been a cornerstone of advanced prompt engineering since its introduction. However, the operational utility of explicit CoT has evolved in response to architectural advancements in frontier models. Modern LLMs frequently execute internal reasoning processes natively, rendering explicit step-by-step instructions redundant for straightforward tasks and introducing unnecessary latency and token consumption.
Nevertheless, explicit chain-of-thought prompting remains highly valuable when processing deeply ambiguous inputs. In scenarios involving conversational reassignments—where an initial task allocation is modified or overturned later in the dialogue—models without explicit reasoning constraints tend to latch onto the earliest plausible mention. Mandating a preliminary trace of ownership evolution across the entire exchange forces the model to maintain comprehensive context before synthesizing its final output.
To balance accuracy gains with economic constraints, engineering teams increasingly look to efficiency-focused variants such as Chain of Draft. By instructing models to articulate reasoning steps in truncated phrases—typically around five words per step—systems can achieve accuracy parity with traditional chain-of-thought prompting while consuming a fraction of the reasoning tokens. This optimization prevents runaway operational costs in large-scale enterprise deployments without compromising the model’s analytical rigor.
Automated Iterative Optimization and Composite Scoring
The apex of prompt optimization methodology involves transitioning from manual, heuristic-based tweaking to automated, algorithmic search processes. Rather than relying on subjective intuition to determine which instructions to add, automated frameworks evaluate candidate prompt fragments against rigorous benchmark test cases using composite scoring algorithms.
CANDIDATE_FRAGMENTS = [
    "If an assignment changes mid-conversation, use the FINAL owner, not the first one mentioned.",
    "If a task gets folded into an existing item later in the conversation, merge it, don't create a duplicate.",
    "If no owner is explicitly assigned, use 'unassigned' rather than guessing.",
    "Do not include general discussion or decisions that aren't concrete action items.",
    "Match each due date to what was actually said, not an assumed default.",
]

def composite_score(extracted: list[dict], ground_truth: list[dict]) -> float:
    """Recall alone misses real quality problems: a wrong owner or a
    fabricated extra item both matter and both get penalized here."""
    result = score_extraction(extracted, ground_truth)
    fabrication_penalty = result["fabricated_items"] * 0.15
    return max(0.0, (result["recall"] * 0.5 + result["owner_accuracy"] * 0.5) - fabrication_penalty)

def optimize(n_iterations: int = 6) -> tuple[PromptCandidate, list]:
    """Hill-climbing: at each step, try adding one unused instruction
    fragment, keep whichever addition improves the score most."""
    current = PromptCandidate(instructions=[])
    current.score = composite_score(simulate_extraction_quality(current), GROUND_TRUTH_ACTION_ITEMS)
    history = [(current.render(), current.score)]
    remaining = list(CANDIDATE_FRAGMENTS)

    for _ in range(n_iterations):
        if not remaining or current.score >= 1.0:
            break
        best_candidate, best_score = None, current.score
        for fragment in remaining:
            trial = PromptCandidate(instructions=current.instructions + [fragment])
            trial_score = composite_score(simulate_extraction_quality(trial), GROUND_TRUTH_ACTION_ITEMS)
            if trial_score > best_score:
                best_candidate, best_score = trial, trial_score
        if best_candidate is None:
            break
        current = best_candidate
        current.score = best_score
        remaining.remove(current.instructions[-1])
        history.append((current.render(), current.score))
    return current, history
In production testing environments, automated hill-climbing optimization algorithms systematically evaluate incremental additions to a baseline prompt. By assessing metrics such as recall, owner accuracy, and strict penalties for fabricated items, the system isolates the minimum effective set of instructions required to achieve optimal performance. Empirical trials demonstrate that automated optimization frequently discovers streamlined, highly effective constraint combinations that human engineers would likely overlook in favor of bloated, multi-paragraph prompts.
Broader Implications for Enterprise AI Integration
The maturation of prompt optimization from an informal art form into a structured engineering discipline reflects the broader professionalization of artificial intelligence deployment. As enterprises move past initial proof-of-concept phases and into mission-critical production workflows, the tolerance for probabilistic error diminishes significantly. Unverified prompts that yield plausible-looking but subtly flawed outputs introduce systemic risks into automated business logic, data pipelines, and decision-support systems.
By adopting systematic optimization strategies—ranging from Pydantic schema validation and persona calibration to diversity-aware few-shot selection and automated hill-climbing search—organizations can establish verifiable quality controls for generative AI applications. This empirical methodology transforms prompt tuning from an exercise in speculative linguistics into a disciplined software engineering practice, ensuring that LLM deployments meet the rigorous reliability standards demanded by modern enterprise architecture.
Related posts: