The deployment of small language models (SLMs) in production environments often collides with severe hardware constraints, transforming what should be rapid text-processing pipelines into sluggish operations. In narrow automation scenarios—such as classifying customer support tickets or parsing structured data—engineers frequently encounter bottlenecks that stem not from the computational complexity of the models themselves, but from inefficient memory management and suboptimal data scheduling. Across the artificial intelligence industry, developers striving to maximize throughput on edge devices or modest local hardware have increasingly focused on micro-optimizations that eliminate hidden sources of resource waste. This engineering challenge forms the core of a broader technical initiative to extract maximum performance from compact architectures like the Qwen2.5-0.5B-Instruct model without sacrificing predictive accuracy.
To understand the magnitude of the efficiency problem, one must examine how small models behave during inference on standard consumer or edge hardware, such as an Apple Silicon M2 MacBook Air equipped with 24GB of RAM and a 16-core Neural Engine. When processing a dataset of text prompts one item at a time—a common baseline approach in naive script implementations—the hardware immediately falls into a memory-bandwidth-bound state. Rather than keeping the arithmetic units of the processor fully occupied with heavy calculations, the system is forced to stream every single parameter weight out of memory just to generate a response for a single sequence. Once that sequence is complete, the hardware clears the slate and repeats the heavy weight-reading process for the next item, leaving the computational cores sitting largely idle during the transitions.
This hardware starvation becomes even more pronounced when scaling up to datasets containing hundreds or thousands of text inputs. Historically, data scientists have attempted to resolve this through batching, processing multiple sequences simultaneously to amortize the heavy cost of weight-loading across a larger computational workload. However, traditional batching introduces its own systemic inefficiency through the necessity of padding. Because neural network frameworks require uniform tensor dimensions, all sequences within a given batch must be padded with placeholder tokens to match the length of the longest item in that specific group. In real-world natural language processing tasks, text length distributions typically exhibit a long tail: while the median prompt might consist of fewer than one hundred tokens, the maximum length in a large dataset could easily stretch to several hundred tokens. Padding every batch to match a global maximum results in vast amounts of computational power being squandered on meaningless padding tokens rather than actual semantic data.
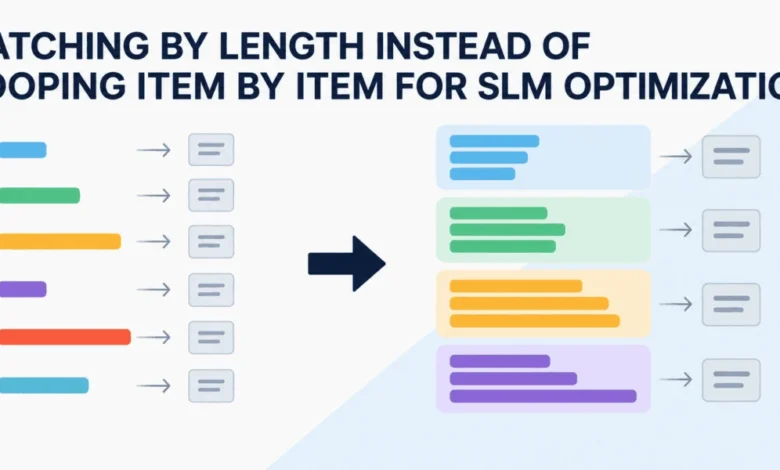
The engineering breakthrough designed to bypass this limitation relies on length-bucketed batching. By sorting the entire dataset by token length prior to forming batches, developers ensure that each batch is composed of similarly sized text items. Consequently, individual batches pad only to their own local maximums rather than a cumbersome global ceiling. This structural adjustment drastically reduces the proportion of wasted computational cycles spent processing blank tokens, aligning the workload more closely with the hardware’s optimal operating capacity.
To quantify the performance gains of this methodology, benchmarks utilizing the Qwen2.5-0.5B-Instruct model running in float16 precision via Hugging Face Transformers provide clear empirical evidence. In a baseline simulation modeling 600 support tickets with a heavily skewed length distribution—ranging from a minimum of 48 tokens to a maximum of 449 tokens, with a median of 94 tokens—processing the tickets strictly one by one required 144.35 seconds, achieving a throughput of approximately 4.2 items per second. In this sequential execution mode, the overhead calculation indicated that padding every item to the global maximum would have processed nearly 3.7 times the necessary volume of tokens, illustrating the profound inefficiency of unmanaged pipelines.
Implementing length-bucketed batching with a batch size of 32 fundamentally transforms these metrics. When the dataset is pre-sorted by token length and processed through organized batches, the total execution time for the exact same 600 tickets drops to 79.60 seconds, nearly doubling the processing speed to 7.5 items per second on the identical hardware configuration. Crucially, the padding overhead—measured by tracking the ratio of real tokens to total processed tokens—plummets to just 7.6 percent. Verification probes comparing the batched outputs against unearned single-item executions confirm a 100 percent agreement rate across tested length distributions, demonstrating that the speedup is achieved without incurring accuracy regressions.
The operational implications of these findings extend far beyond benchmark tables, offering critical guidance for software architects deploying automated text-processing systems in production environments. In enterprise settings where computational budgets dictate operational margins, doubling throughput without upgrading physical hardware translates directly into reduced cloud infrastructure costs and lower latency for end-users. Furthermore, the techniques demonstrated across this optimization series—ranging from constraining output spaces and utilizing key-value caches for prompt prefixes to implementing length-sorted batching—highlight a vital software engineering principle: maximizing AI performance often relies less on raw model scaling and more on meticulous systems engineering.
Nevertheless, engineers attempting to synthesize these advanced optimizations must proceed with caution. Complex interactions can arise when combining multiple performance strategies simultaneously. For instance, integrating prompt-prefix caching with length-bucketed batching requires careful tensor manipulation, as caching mechanisms typically assume a batch dimension of one. Developers must explicitly expand and crop key-value tensors to match batch configurations and rigorously verify output predictions against baseline paths to prevent silent failures. As artificial intelligence integration deepens across diverse industrial sectors, the ability to harmonize model architecture with underlying hardware mechanics will remain a defining competency for high-performance software development.