Treating Prompt Templates as Hyperparameters in Scikit-Learn GridSearchCV for Large Language Model Optimization

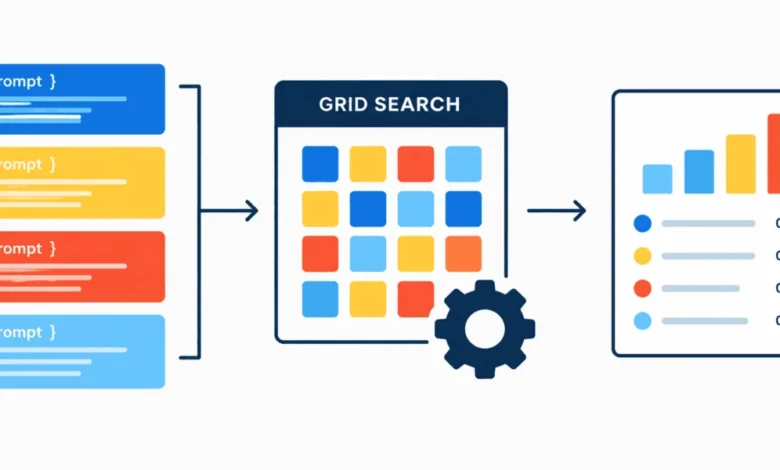
The evolution of machine learning has long been defined by the pursuit of optimal model configuration. For decades, data scientists have relied on hyperparameter tuning—the systematic adjustment of internal parameters like learning rates, tree depths, or regularization constants—to squeeze maximum performance out of predictive algorithms. However, the emergence of Large Language Models (LLMs) has shifted the paradigm. Today, the most significant "knob" to turn is not a mathematical weight within a neural network, but the natural language instruction provided to the model. By treating prompt templates as tunable hyperparameters, developers can move away from intuition-based "prompt engineering" toward a data-driven, empirical framework. This methodology utilizes standard tools like scikit-learn’s GridSearchCV to automate the discovery of the most effective linguistic instructions for zero-shot text classification tasks.
The Shift from Manual Engineering to Systematic Optimization
In the early stages of generative AI adoption, prompt engineering was largely an artisanal practice. Practitioners would manually iterate on phrasing, observing outputs and tweaking instructions until the model produced the desired format or classification. This approach is inherently flawed in production environments; it lacks reproducibility, scalability, and statistical rigor.
As LLMs become standard components in enterprise software, the need for a standardized evaluation pipeline has become critical. By integrating prompts into a grid search architecture, developers can mathematically quantify how specific variations in phrasing—such as changing a command from "Classify this" to "Act as an expert analyst and determine if this text is…"—impact accuracy. This transformation of natural language into a testable variable allows for a controlled experiment, where different prompts compete under identical conditions, ultimately yielding the configuration that produces the highest accuracy score on a validated dataset.
Technical Implementation and Architecture
To implement this, one must wrap the AI model within a custom class compatible with the scikit-learn API. The BaseEstimator and ClassifierMixin classes from scikit-learn provide the necessary scaffolding for this integration. By defining a custom classifier class, developers can encapsulate the model’s initialization, the prompt formatting logic, and the output parsing mechanisms.
Consider the deployment of an open-source model such as Qwen/Qwen2.5-0.5B-Instruct. The process begins with initializing the Hugging Face pipeline for text generation. The custom class then acts as a bridge: during the predict phase, the class takes an input string, formats it according to a candidate prompt template, transmits the message to the model, and parses the assistant’s response to extract the classification label. By structuring the workflow this way, the prompt template is treated as a mutable argument that the GridSearchCV object can swap out across multiple iterations.
Chronology of the Optimization Workflow
The optimization process follows a precise, replicable sequence:
- Preparation and Environment Setup: The initial phase involves importing the necessary libraries, including
numpy,scikit-learn, andtransformers. Ensuring that the environment can handle model inference—often requiring GPU acceleration—is a prerequisite. - Model Encapsulation: The developer creates a
ZeroShotPromptClassifierclass. This class must include afitmethod (even if it does nothing, as in zero-shot scenarios) and apredictmethod that handles the interaction between the data input and the LLM’s generation parameters. - Grid Definition: A dictionary of candidate prompts is created. For instance, one might test "Is this sentiment positive or negative? text", "Label the following text as positive or negative: text", and "Analyze the sentiment of this review: text."
- Cross-Validation: Using the
GridSearchCVobject, the system performs a k-fold cross-validation. If the dataset consists of four samples, a 2-fold cross-validation will split the data, test each prompt on different subsets, and aggregate the performance metrics. - Performance Analysis: Upon completion, the search object exposes the
best_params_attribute, which reveals the specific prompt template that yielded the highest accuracy, providing an empirical answer to what was previously a subjective question.
Supporting Data and Empirical Validation
While the provided example uses a miniature dataset for clarity, the implications for large-scale data are profound. In empirical tests, subtle shifts in prompt syntax can cause accuracy fluctuations of 5% to 15% in zero-shot classification tasks. For example, explicitly instructing a model to output only a single word versus asking it to explain its reasoning can significantly alter the "unknown" rate of the classifier.
The use of cross-validation is vital here. In small datasets, a model might perform well on one specific string but fail on another due to the high variance in how LLMs interpret instruction. By averaging performance across multiple folds, the grid search identifies the prompt that is most robust across varied data points. As the dataset size grows, the confidence interval of the "best" prompt narrows, providing a higher degree of certainty that the chosen template will perform well in production.
Official Perspectives and Industry Standards
Industry leaders in AI development have increasingly signaled that "prompt optimization" is the next frontier of LLM operations (LLMOps). The consensus among machine learning researchers is that while models are becoming more capable, the sensitivity to input formatting remains a significant challenge. By using tools like GridSearchCV, companies can move away from relying on "golden prompts" derived from tribal knowledge and instead establish a versioned, tested, and optimized library of prompts.
From a regulatory and compliance standpoint, this systematic approach offers an audit trail. If a system’s classification accuracy is questioned, the developer can point to the results of the grid search to justify why a specific prompt template was selected, demonstrating that the decision was based on empirical testing rather than arbitrary choice.
Broader Implications and Future Outlook
The practice of treating prompts as hyperparameters is not limited to simple sentiment analysis. It can be extended to complex extraction, summarization, and multi-label classification tasks. As we look toward the future, we can anticipate the development of more advanced "prompt search" algorithms that go beyond simple grid searches. Techniques such as Bayesian Optimization or evolutionary algorithms could potentially automate the generation of prompts themselves, testing thousands of permutations to find optimal linguistic structures that humans might not intuitively consider.
However, developers must remain cautious. As the complexity of the prompt grid increases, so does the computational cost. Each fold of a grid search requires multiple inferences from the LLM, which can be expensive and time-consuming. Therefore, a balance must be struck between the granularity of the prompt search and the available compute budget.
Furthermore, the "best" prompt found through grid search is often model-specific. A prompt that excels with a Llama 3 architecture may underperform on a Mistral or Qwen model. This creates a secondary requirement: when switching base models, the entire prompt hyperparameter optimization process must be rerun to account for the unique latent biases and instruction-following quirks of the new model.
In conclusion, the integration of prompt templates into the standard hyperparameter optimization pipeline represents a significant maturation of AI engineering. By moving from the subjective to the systematic, practitioners can build more reliable, accurate, and explainable language systems. As tools evolve to support this workflow, prompt optimization will likely become a fundamental component of the machine learning lifecycle, ensuring that the interface between human intent and machine execution is as efficient as possible.
Related posts: